LLM integration for Indian businesses: three patterns, 2026 OpenAI, Claude, Gemini and Sarvam prices in rupees, India data rules and a build checklist.
- Published
- Updated
- Reading time
- 17 minutes
Drafted with AI tools; researched, edited and approved by Althameem Ali. Our editorial policy
On this page · 11 sections
- What does LLM integration mean for a business system?
- Which pattern fits: a prompt, retrieval over your own data, or tools and agents?
- Which model: OpenAI, Claude, Gemini or Sarvam?
- Where is the data processed, and what does Indian law expect?
- What does it cost to run?
- How do you keep answers accurate and inside each user's permissions?
- What are the security risks?
- A build checklist
- Frequently asked questions
- What to do next
- Changelog
Full disclosure: we build custom software, and the team behind Marketlube built Xale CRM and its AI assistant, the worked example in this guide. Every price and rule below links to its source, read on 4 October 2026, and every assumption in the cost model is stated so you can change it.
This guide is for owners who want AI inside their CRM, ERP or portal, and for the developers who will build it. It covers the patterns, the models and their prices in rupees, where the data goes and what Indian law expects, running costs, accuracy, security and a build checklist.
What does LLM integration mean for a business system?#
A large language model (LLM) is the engine behind tools like ChatGPT, Claude and Gemini. Integration means your own software sends it text, and sometimes images or audio, through an API, gets a result back and uses that result inside a real workflow: a summary saved on a lead, a draft quote waiting for approval, an answer to a manager's question, a field filled from a scanned bill.
The difference from a team using ChatGPT in a browser is control. In an integration, your software decides what data the model sees, which user is asking, what the model may do, and what gets logged. That is also where the work is. The model call itself is a few lines of code; deciding what goes into it, and what happens to what comes out, is the product.
For where these features pay off in practice, our guides to AI in CRM and AI in ERP list the use cases by function. This guide is about how to build them.
Which pattern fits: a prompt, retrieval over your own data, or tools and agents?#
Almost every business AI feature is one of three patterns, or a combination:
Start with the simplest pattern that works. A prompt is cheap, predictable and easy to test. Retrieval adds a search step and a store of documents to keep current. Tools give the most power and the most risk, because the model now chooses actions; every tool should do one narrow thing, check the user's permissions itself, and leave anything irreversible for a person to approve. The Model Context Protocol (MCP), an open standard for connecting AI models to tools and data, is becoming the common way to expose those tools, and ERPs such as Odoo 20 now ship MCP connections, as our ERP guide notes.
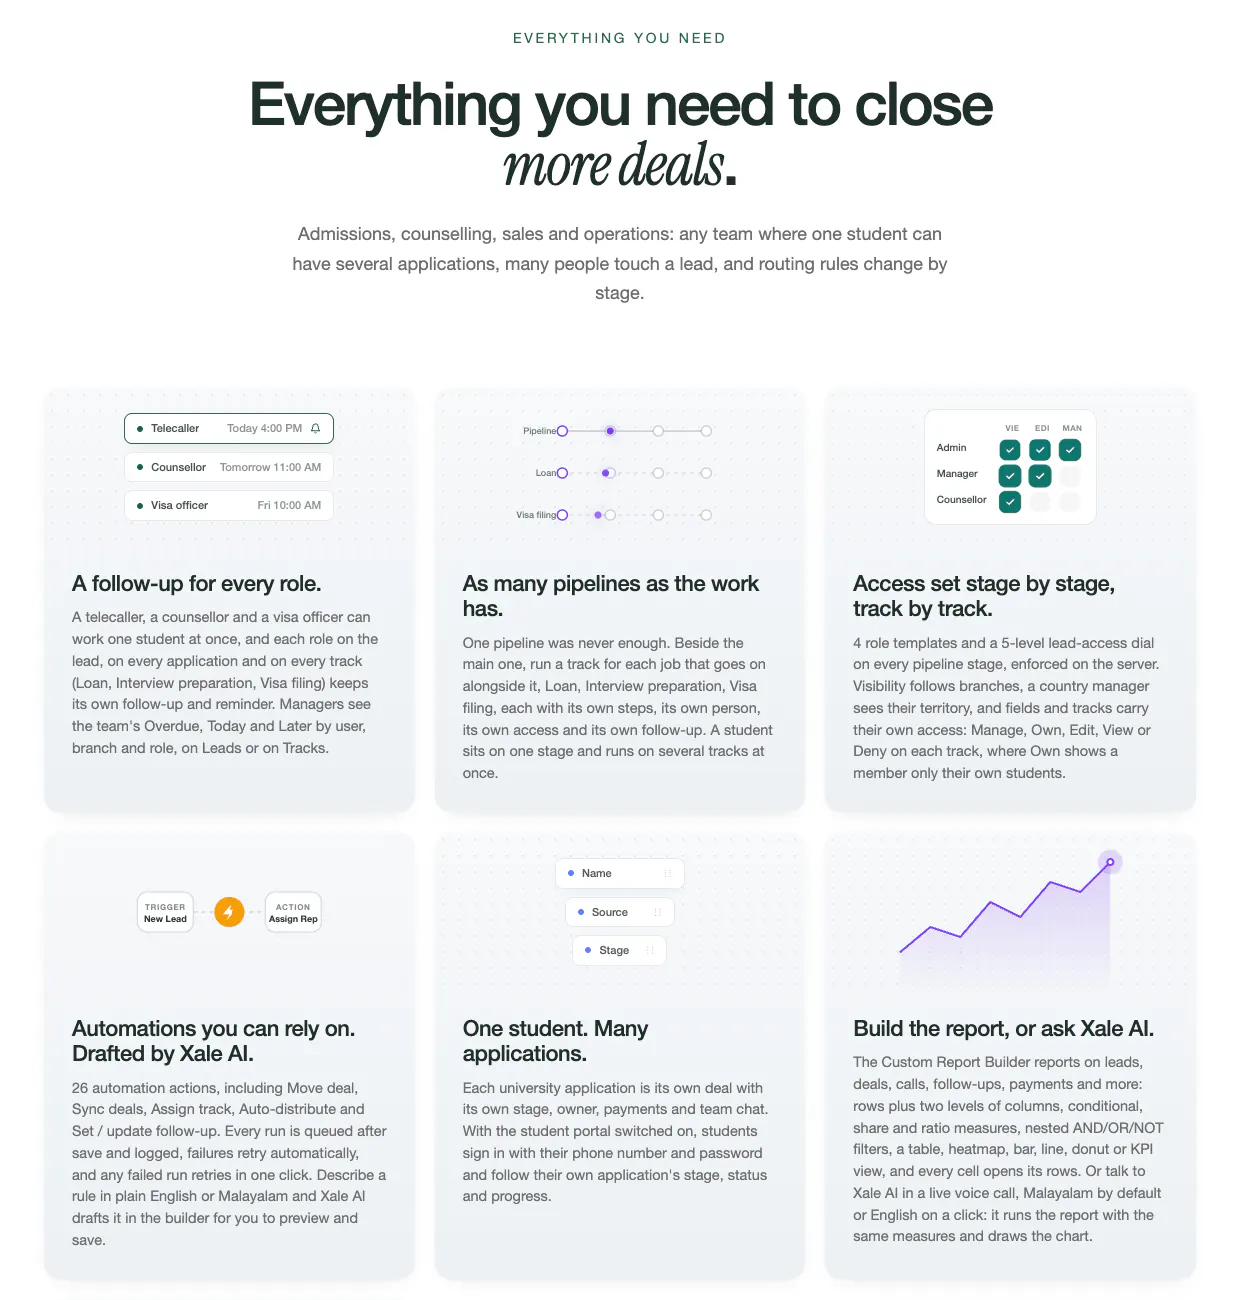
Xale is our worked example. Its case study describes Xale AI as answering questions from a team's own CRM data, in Malayalam or English (Xale case study). Xale's own AI CRM page (opens in a new tab) (updated 25 September 2026, read 4 October 2026) adds three details that matter to anyone building the same thing: lead, deal and follow-up answers "follow the asking user's visibility", while call counts and the top-caller ranking cover the whole workspace; every answer lists what it looked up and which filters it applied, so anyone can check a number; and "models come from Anthropic, Google Gemini or OpenRouter, managed by Xale". From the outside, that is the tools pattern done carefully: the model asks the CRM for data through lookups the CRM controls, and the person asking can check the working. It is the pattern we start from for AI assistants on a business's own data.
It is also where our own builds start. A model that can call tools still needs something to call: a place to save a call or a chat as a lead with its context, pass it to a person and count it in the next day's reports. We don't write that again for each client. We build on the platform Xale runs on (opens in a new tab). It already has the leads, follow-ups and call records an assistant reads and writes, and the roles, automations and reports that govern them (reported by our team), so the work left is the model and the tools it may call. Besides the assistant, xale.in describes a voice layer on the same records: Xale's telecaller (opens in a new tab), a call a person starts on one student.
Which model: OpenAI, Claude, Gemini or Sarvam?#
List prices per million tokens (a token is a small chunk of text, often part of a word), as published on 4 October 2026:
Sources: OpenAI pricing (opens in a new tab), Anthropic's Claude pricing (opens in a new tab), Gemini API pricing (opens in a new tab) (last updated 1 October 2026), Sarvam pricing (opens in a new tab) and Sarvam's model list (opens in a new tab), all read 4 October 2026. OpenAI and Anthropic both take 50% off for batch processing, work that can wait for results.
How to choose:
- Match the model to the job, not the brand. Summaries, classification and field extraction usually work well on the small models. Long reasoning, tricky documents and multi-step agents justify the larger ones. Many systems use two: a small model for routine calls and a larger one for the hard cases.
- Test on your own data. Take 50 to 100 real examples, run them through two or three models, and score the answers. A benchmark someone else ran on English text tells you little about your Malayalam call notes.
- Test Malayalam and Arabic explicitly. Sarvam lists Malayalam (ml-IN) for its 105B language model, its Saaras v4 speech-to-text and its Bulbul v3 text-to-speech, with speech-to-text at ₹30 an hour and text-to-speech at ₹30 per 10,000 characters. For mixed Malayalam and English calls, Xale's page says it sends the audio to Google Gemini with a Malayalam and English prompt, with OpenAI's Whisper as the fallback. Whatever you pick, check names, places and rupee amounts in the output.
- Use current APIs. OpenAI shut down its Assistants API on 26 August 2026 in favour of the Responses and Conversations APIs, per its deprecations page (opens in a new tab). Older tutorials still describe the retired route.
Where is the data processed, and what does Indian law expect?#
Every API call sends the data in it to the model provider. If that data includes your customers' names, numbers or conversations, two questions follow: in which country is it processed, and is it used to train anyone's model?
Processing inside India. The options are growing but uneven:
- Claude on Amazon Bedrock. Since 29 September 2026, Claude Opus 5, Claude Sonnet 5 and Claude Haiku 4.5 are available with in-country inference, and "requests route only between ap-south-1 and ap-south-2", AWS's Mumbai and Hyderabad regions (AWS, 29 September 2026 (opens in a new tab)). The newest Claude models were not on that list.
- Gemini through Google Cloud. Google India said on 14 July 2026 that Gemini 3.5 Flash is available through the Gemini Enterprise Agent Platform and the Gemini Enterprise app "with strict in-country machine learning processing commitments" (Google India blog (opens in a new tab)).
- OpenAI models on Microsoft Azure. Regional deployments in Azure's South India region process data in that region, but only for older models such as gpt-4.1-mini and gpt-4o; newer models such as gpt-6.1-sol are offered there as Data Zone deployments, processed anywhere in Asia Pacific (Microsoft Learn (opens in a new tab), 3 September 2026).
Regional processing can cost more. OpenAI charges a 10% uplift on its regional processing endpoints for models released on or after 5 March 2026, and Anthropic prices US-only inference at 1.1 times its standard rates.
Training on your data. Read each provider's terms. Google's own pricing page is a clear example: content on the Gemini API's free tier is "used to improve our products", and paid-tier content is not. Never send customer data through a free tier.
What Indian law says. The Digital Personal Data Protection Act, 2023 (opens in a new tab) lets the Centre restrict transfers of personal data to countries it notifies (section 16), rather than listing approved ones. The DPDP Rules, 2025 (opens in a new tab) allow transfers abroad, subject to requirements the Centre may set on making data available to a foreign State (Rule 15), and let the Centre require significant data fiduciaries to keep specified data inside India (Rule 13(4)). A model provider handling your customers' data is your Data Processor, so the business stays responsible for it, and the main duties apply from May 2027. Our DPDP compliance checklist turns those rules into steps for lead and CRM data.
MeitY's India AI Governance Guidelines (opens in a new tab) (November 2025) concluded that "a separate law to regulate AI is not needed given the current assessment of risks", but asked industry to "publish transparency reports" and "provide grievance redressal mechanisms", and recommended human-in-the-loop checks at critical decision points. For a business system, that translates into telling users when AI wrote something, giving them a way to complain, and keeping a person on decisions that matter.
What does it cost to run?#
The formula is simple: tokens per task, times tasks a month, times the price per token. Here are three workloads, with assumptions you can replace with your own:
- Call summaries: 10,000 a month, each 3,000 input tokens (transcript and instructions) and 300 output tokens.
- Questions over your data: 20,000 a month, each 6,000 input tokens (question, instructions and retrieved records) and 400 output tokens.
- Agent tasks: 2,000 a month, each five model calls averaging 8,000 input and 500 output tokens.
Prices read on 4 October 2026, dollars converted at ₹95.99 (the FBIL reference rate for 1 October 2026 on the Reserve Bank of India's website (opens in a new tab)), before caching, batch discounts, regional surcharges and GST. Gemini 3.8 Flash doubles on 1 January 2027, to about ₹6,480, ₹23,040 and ₹15,120.
What the table shows:
- The model choice moves the bill a hundredfold. The same 20,000 questions cost ₹1,540 or ₹1.54 lakh a month, so test whether the cheaper model is good enough before defaulting to the biggest.
- Input tokens dominate. Retrieval and agents send far more text in than they get back, which is why caching matters: OpenAI lists cached input for gpt-6.1-sol at $0.10 against $2, and Anthropic lists cache reads for Sonnet 5.5 at $0.20 against $2. Repeated instructions and documents get much cheaper.
- Work that can wait is half price. Overnight summaries or bulk tagging can go through batch processing at 50% off.
- Tokens are not the whole bill. Add hosting for the search index, logging, testing time and the developers who maintain it. Our custom software cost guide covers the build and running costs around the AI. For workflow and agent builds in particular, our AI automation cost guide gives sellers' published prices and the monthly upkeep.
Count tokens on your own samples before you budget. The same message can produce quite different token counts in Malayalam and in English, and from one model's tokenizer to the next.
How do you keep answers accurate and inside each user's permissions?#
NIST's Generative AI Profile (opens in a new tab) (NIST AI 600-1, July 2024, page updated 8 April 2026) lists twelve risks of generative AI, among them confabulation: "confidently stated but erroneous or false content", known colloquially as hallucinations. In a business system, five habits keep it in check:
- Answer from your data, not the model's memory. Retrieval or tools should supply the facts; the instructions should tell the model to say "I don't know" when the data doesn't contain the answer.
- Enforce permissions in code, before the model sees anything. If a telecaller may see only their own branch, the search or the tool must return only that branch. Never rely on an instruction like "don't reveal other branches"; a determined user can talk a model out of instructions.
- Show the working. Like Xale's answers, show which records or filters an answer used, so a person can check a number in one tap.
- Test before and after every change. Keep a set of 50 to 100 real questions with known answers, and re-run it whenever you change the model, the instructions or the data.
- Keep a person on anything irreversible. Drafts, flags and answers can go straight to users; messages to customers, payments and record deletions should wait for approval.
What are the security risks?#
The OWASP Top 10 for LLM Applications 2025 (opens in a new tab) (published in November 2024) is the standard checklist. The entries that bite business systems most often:
Agents carry their own risks, from hijacked goals to tool misuse, which OWASP covers in a separate Top 10 for Agentic Applications (opens in a new tab), released on 9 December 2025.
A build checklist#
Frequently asked questions#
What is LLM integration?#
It is connecting a large language model to your own software through an API, so the model can summarise, draft, answer questions or take approved actions inside your workflows, using your data and your permission rules rather than a separate chat window.
Is retrieval (RAG) better than fine-tuning for business data?#
For most business systems, start with retrieval. It answers from your current records and documents, can respect each user's permissions at search time, and needs no retraining when the data changes. Fine-tuning changes how a model writes or classifies, not what it knows about this morning's leads.
How much does it cost to run AI features in business software?#
At list prices read in October 2026, 10,000 call summaries a month cost from about ₹430 on OpenAI's gpt-6-luna to about ₹43,200 on the top-tier models, and 20,000 questions over your own data from about ₹1,540 to ₹1.54 lakh. Caching and batch processing reduce these; hosting, logging and maintenance add to them.
Can business data stay in India when you use AI models?#
Partly. AWS routes Claude Opus 5, Claude Sonnet 5 and Claude Haiku 4.5 only between its Mumbai and Hyderabad regions under in-country inference, Google offers Gemini 3.5 Flash with in-country processing commitments, and Azure processes older OpenAI models inside its South India region. Many of the newest models are not yet available with India-only processing.
What to do next#
Pick one workflow where your team retypes, summarises or searches every day, and write down the data it needs and who may see it. That one page decides the pattern, the model and the cost. If you want help building it into your CRM, ERP or portal, tell us about the workflow and we will sketch the pattern, the model shortlist and a monthly running cost before anyone writes code. Or talk it through with Althameem Ali, our co-founder, in a one-hour consultation.
Changelog#
- 2026-10-11: Linked our AI automation cost guide from "What does it cost to run?", for the build and upkeep prices of workflow and agent projects.
- 2026-10-12: Added a paragraph on where our own builds start: AI as the top layer on the Xale platform, where leads, follow-ups, call records, roles, automations and reports already exist (reported by our team), with a link to xale.in's page on its telecaller. One sentence we had quoted from xale.in's AI CRM page is now in our own words, still credited to that page. The paragraph on where our builds start is in this guide's own words, about what a model's tools call, with the same facts.
Related services
Written by
Co-founder, Marketlube
Althameem Ali researched, edited and approved this post. Marketlube is a growth partner in Calicut building brands, websites, CRMs and campaigns for businesses across Kerala, India and the Gulf.